To investigate a key skill set for online learning – Critical Online Reasoning (COR) – and the online information landscape that students access and use when learning and solving COR tasks, the Research Unit draws on an interdisciplinary conceptual and methodological approach.
Across four longitudinal measurement points during students’ undergraduate studies, the FOR investigates COR as a competence, a process, and an interaction between students and their information environment.
COR refers to the ability to strategically search for, critically evaluate, and synthesize high-quality information from diverse online sources. It distinguishes between generic COR skills, which are independent of specialized disciplinary knowledge, and domain-specific COR skills, which rely on disciplinary expertise and discipline-based reasoning.
Multimodal data
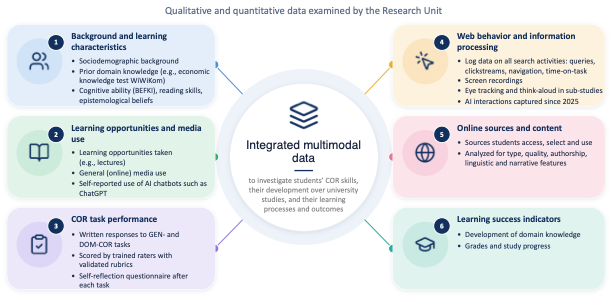
To determine students’ COR levels, their development over university studies, and key COR covariates, the Research Unit examines qualitative and quantitative multimodal data, including:
(1) students’ sociodemographic background and learning characteristics (e.g., prior domain knowledge, general intellectual skills, reading skills, epistemological beliefs), assessed, for example, with the cognitive ability test and the economic knowledge test,
(2) learning opportunities the students have taken (e.g., lectures), their general (online) media use, and their use of AI chatbots such as ChatGPT,
(3) students’ COR task performance, i.e., their written responses to COR tasks, complemented by self-reflection questionnaires after each task,
(4) students’ web behavior and information processing, i.e., log data including all search activities collected during the COR task-solving process (e.g., search queries, clickstreams, website navigation patterns, time-on-task) and screen recordings, complemented by eye tracking and think-aloud protocols in sub-studies,
(5) online sources and information/content the students access, select and use during COR task solving, and
(6) learning outcome indicators, including domain knowledge development, grades and study progress.
Study domains
We investigate COR and online information environments in selected higher-education study domains to allow systematic comparison across disciplines. For this purpose, we focus on two main study domains: medicine and economics. COR performance on generic and domain-specific COR tasks is assessed among students of economics and medicine. We include students of social sciences and physics as comparison groups to examine domain-related differences.
Assessment framework
COR skills are measured through authentic, computer-based performance assessments. Scenario-based tasks immerse students in a realistic situation and ask them to solve a constructed or real (domain-specific) course assignment or information problem – for example, evaluating the claim “Radio mast radiation is harmless to humans” or assessing economic growth in relation to environmental sustainability based on conflicting data.
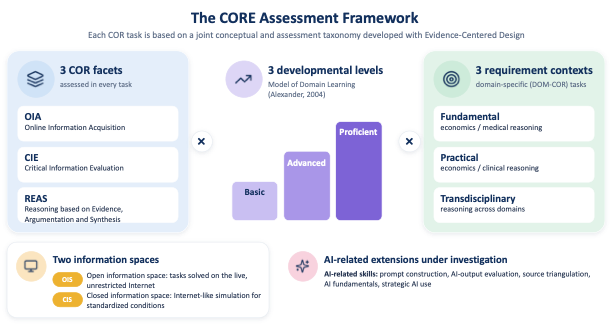
Tasks are administered in two information spaces. In the Open Information Space, students solve the task on the live, unrestricted Internet: they search for and select information, evaluate its credibility and relevance, and integrate multiple sources into evidence-based statements. Closed Information Space tasks use Internet-like simulations to provide more standardized assessment conditions and to enable systematic comparisons between open and controlled information environments.
The assessment framework was developed based on Evidence-Centered Design. Each COR task is based on the joint conceptual and assessment taxonomy and encompasses a multitude of behavioral indicators classified by the three COR facets (OIA, CIE, REAS), three developmental levels (basic, advanced, proficient; based on the Model of Domain Learning by Alexander, 2004), and – specific to the domain-specific COR assessment – three requirement contexts (fundamental reasoning, practical reasoning, transdisciplinary reasoning).
We developed and validated all COR tasks through iterative design cycles involving student feedback, expert reviews, and pilot testing. The current task portfolio comprises seven task scenarios for each of the generic, economics, and medicine domains. The assessment portfolio is documented in CORE Working Paper No. 3.
Trained raters score students’ written responses using validated rubrics. Indicators include the number and quality of sources used, explicit reference to evaluation criteria, the integration of multiple perspectives, and the use of appropriate (disciplinary) arguments. Inter-rater reliability was assessed using established reliability coefficients and exceeds .80 for the reported rating domains. In addition, we are evaluating AI-assisted scoring procedures to complement human ratings.
AI-related skills and practices
Given the growing role of generative AI in learning and information environments, the COR research program is being extended to investigate AI-related skills and practices, including prompt construction, critical evaluation of AI outputs, source triangulation, and the strategic use of AI in research, decision-making, and learning.
Longitudinal study design
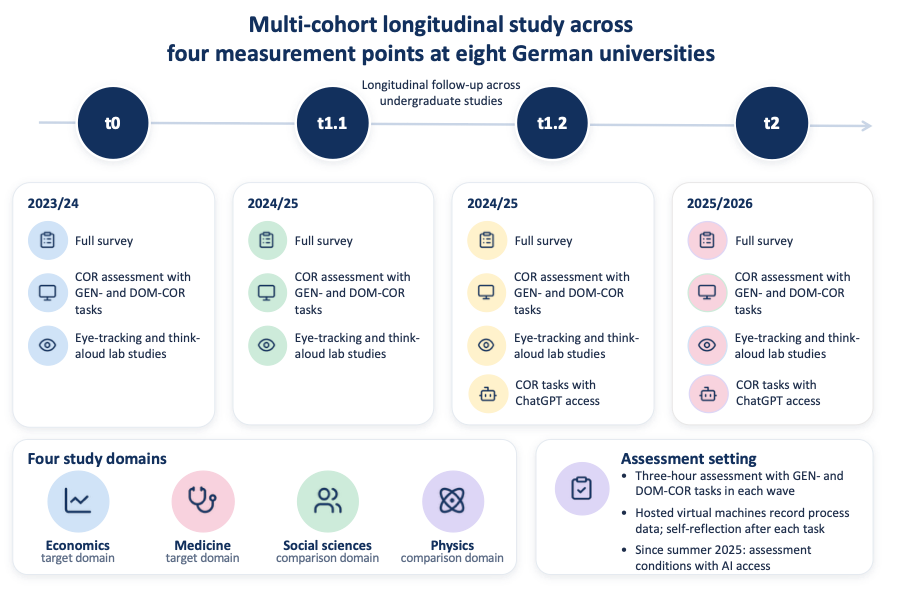
CORE employs a multi-cohort longitudinal design with a panel structure. Since 2023, CORE has followed undergraduate students at eight universities in Germany from their first semester through their undergraduate studies across four measurement points to capture individual growth trajectories and disciplinary differences in COR development. A stratified sampling procedure supports balanced representation across disciplines and stages of study.
Full survey. Each measurement point includes a full survey. At the start of the winter term 2023/24, 2024/25, and 2025/26, we invited beginning students to complete the 15-minute online survey during introductory courses, using their own devices or on-site.
COR assessment. In each wave, students from the survey sample complete a three-hour assessment consisting of generic and domain-specific COR tasks. Students accessed the Internet-based assessment via hosted virtual machines on the CORE assessment platform, which recorded their process data.
Sub-studies. Fine-grained analyses of COR task-solving processes are carried out in lab studies with eye tracking and retrospective think-aloud protocols at the process data labs in Frankfurt (GU), Munich (LMU), and Mainz (JGU). In a three-hour lab session, each participant solves one generic and one domain-specific COR task, each followed by a retrospective think-aloud on selected excerpts of their task processing.
Generative AI. AI use has been restricted during COR tasks to preserve the validity of the skill assessment. In summer 2025, CORE introduced AI-augmented assessment conditions in which students were allowed or even required to use AI tools during task completion. Their interactions with AI tools are captured through log files, screen capture, and self-reflection questionnaires, enabling the analysis of prompt construction, source triangulation, and critical evaluation of AI output. A comparative study examined COR task performance with and without access to ChatGPT among participants from the main COR sample. A cross-project GenAI working group coordinates this research.
Analyses
Analyses in the FOR focus on (1) students’ COR performance, development, and processes, (2) the information landscape students encounter online, and (3) the integration of both.
COR performance and development. Longitudinal analyses examine whether generic and domain-specific skills develop interdependently over time, how they relate to individual characteristics such as prior knowledge and intellectual abilities, how contextual factors such as course attendance and academic experiences are related to their development, and how COR relates to students’ learning outcomes.
Information landscape. When students complete COR tasks on the Internet, the system records and stores all sources visited and used in a common data corpus. The Research Unit focuses on the characteristics of the logged sources that students select and use as a basis for their responses, particularly features expected to contribute to students’ decisions to rely on those sources and information. For example, sources may promote/claim or diminish/contest qualities such as author confidence, positive or negative stance, cues for (high/low) credibility, loadedness or bias.
Coding manuals are compiled for the topic areas and range of logged sources: a codebook captures general website characteristics (e.g., date, genre, visual elements, relevance) and the completeness, accuracy, balance and comprehensibility of content, applied by teams of trained coders with reliability coefficients between .80 and 1.00.
Research approaches range from qualitative content coding of media products to qualitative typological and quantitative computational linguistic analyses (including machine learning) and to analyses of narrative structures such as metaphors and the reconstruction of latent meanings.
Process analyses. Analyses of the task-solving process – combining logfile analyses, screen-based process data, eye tracking on specific websites, think-aloud protocols and reconstructive approaches – aim to uncover process indicators of (un)successful COR performance.
Data integration. The Research Unit has established a multimodal research infrastructure that integrates COR performance data with logfile information on students’ online behavior, screen recordings, human and partially automated performance ratings, assessments of the websites consulted and, in sub-studies, eye-tracking, think-aloud and process reconstruction data.
A multimodal database links text and process data across projects. This enables cross-project analyses linking the information a student encounters with the search and navigation behavior through which they accessed it, the evaluation processes applied to it, its subsequent integration into reasoning, and the resulting task performance.